


Helping More People Start Great Companies
Y Combinator helps more people start great companies. Through Startup School, it makes practical startup education available to anyone, for free. At Wafer, we want more people building companies that improve the world. We’re extremely proud to support YC’s work.
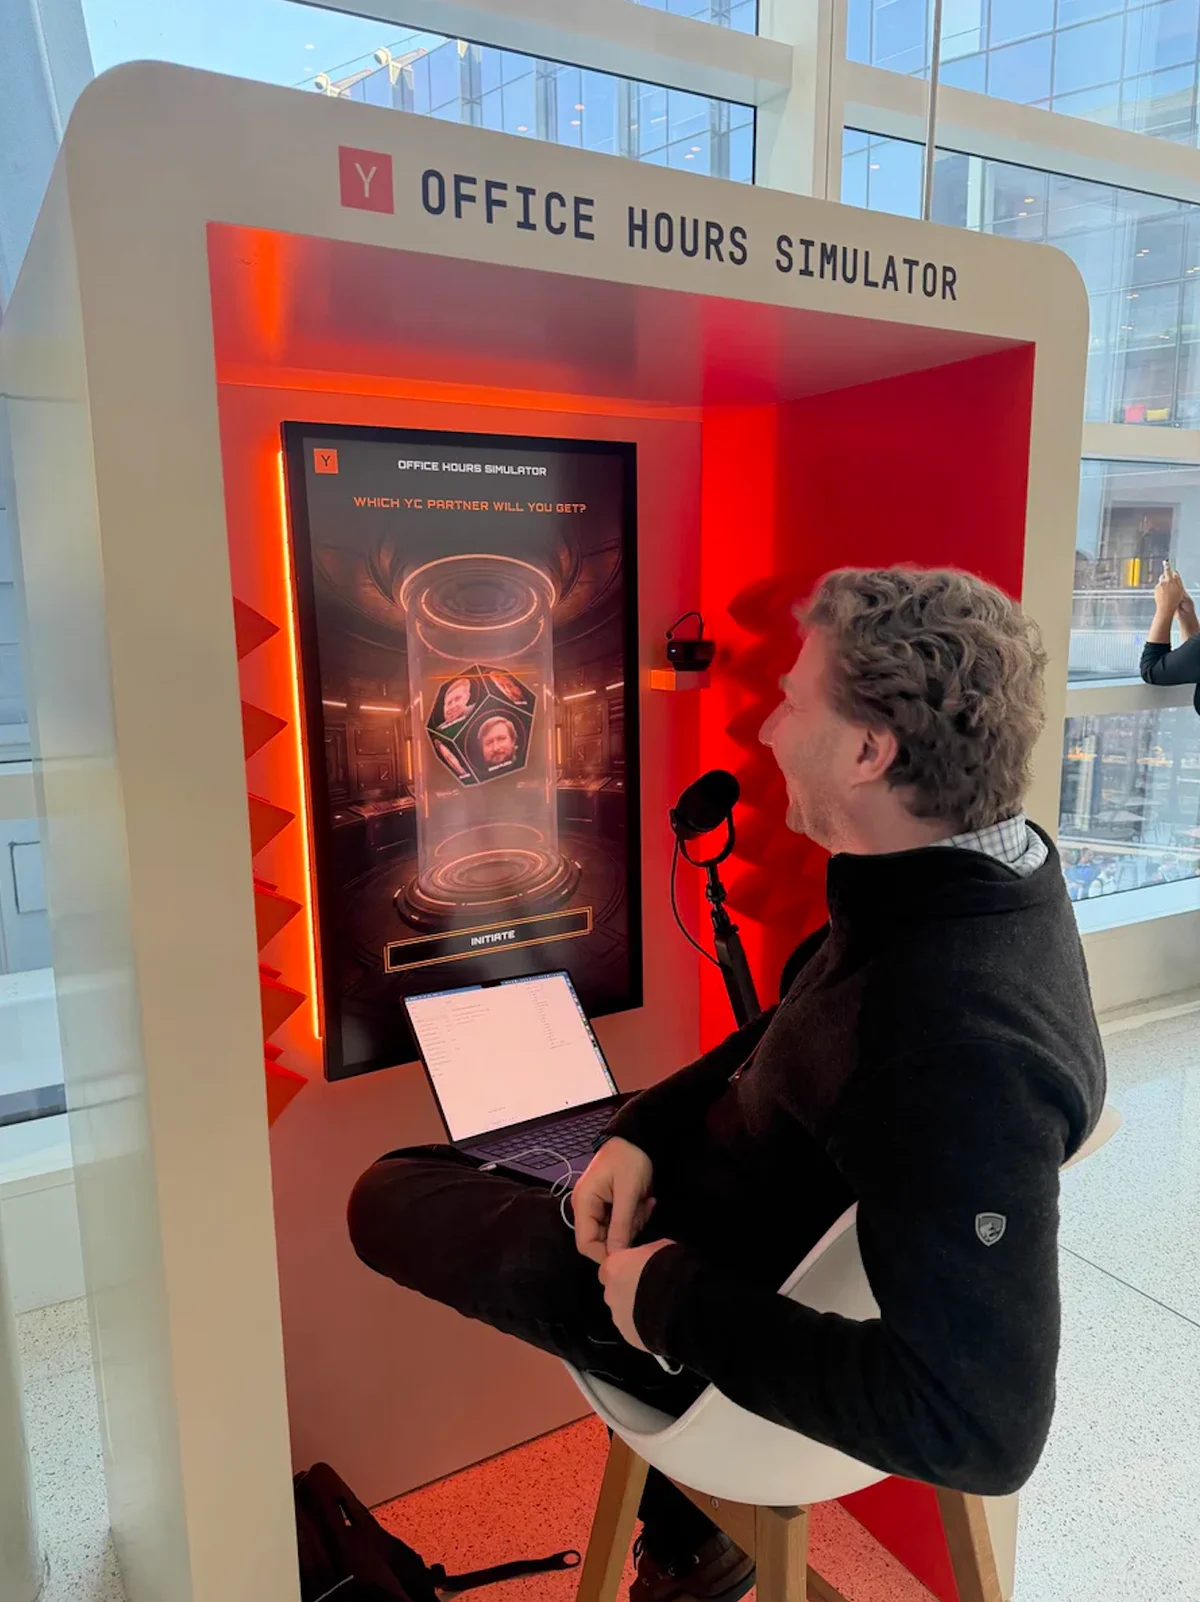
YC’s Office Hour Simulator lets users talk to AI versions of YC partners. The booth works like a video call: users ask questions and get spoken answers.
Wafer provides the LLM inference behind those answers.
Watch the simulatorHow YC Landed at the Lowest Latency
YC had been testing lightweight Gemini and OpenAI models for the simulator. It needed useful answers with low enough latency for a spoken conversation. The avatar waits for the LLM before it can answer, so inference latency directly affects how quickly it can respond.
A Dedicated GLM-5.2 Deployment
We worked with YC to deploy GLM-5.2 on a dedicated Wafer endpoint. Wafer agents tuned the serving setup for YC’s request rate, cache usage, and prompt and response lengths.
YC then launched a three-way production test against GPT-4.1 mini on OpenAI and Gemma 4 31B on Cerebras. The evaluation covered answer quality, latency, and conversation duration.
Lower Latency, Longer Conversations
In a production test covering 4,168 LLM turns across the three configurations, GLM-5.2 on Wafer averaged 379 ms of latency: 31% lower than the OpenAI configuration and 44% lower than the Cerebras configuration.
Average LLM latency
Lower is better
- WaferGLM-5.2379 ms
- OpenAIGPT-4.1 mini546 ms
- CerebrasGemma 4 31B674 ms
4,168 LLM turns across all three configurations.
Conversations lasting 10 to 15 minutes
Higher is better
- WaferGLM-5.241%
- OpenAIGPT-4.1 mini23%
- CerebrasGemma 4 31B9%
Share of sessions in the 10 to 15 minute duration bucket.
Different models and providers; customer measurements.
YC reported that users talked to Wafer-backed avatars for 2.5 minutes longer on average. Sessions lasting 10 to 15 minutes accounted for 41% of conversations on Wafer, compared with 23% on OpenAI and 9% on Cerebras.
For YC, the result was faster responses and more time spent with its AI partners. We’re proud to provide the inference supporting these tools for founders.
Build Your Voice Application With Wafer
Talk to Wafer about a dedicated deployment for your voice application.